
BlackRock Deploys Anthropic AI Tools For Financial Market Systems
High-performance compute clusters face growing memory and thermal bottlenecks. Infrastructure updates are vital to process heavy workloads.

High-performance compute clusters face growing memory and thermal bottlenecks. Infrastructure updates are vital to process heavy workloads.

Safety monitoring systems consume up to twenty percent of inference power. Thermal throttling further degrades enterprise workloads.

Data center thermal limits can stall GPU execution during peak model usage. Hardware failure modes endanger real-world safety systems.
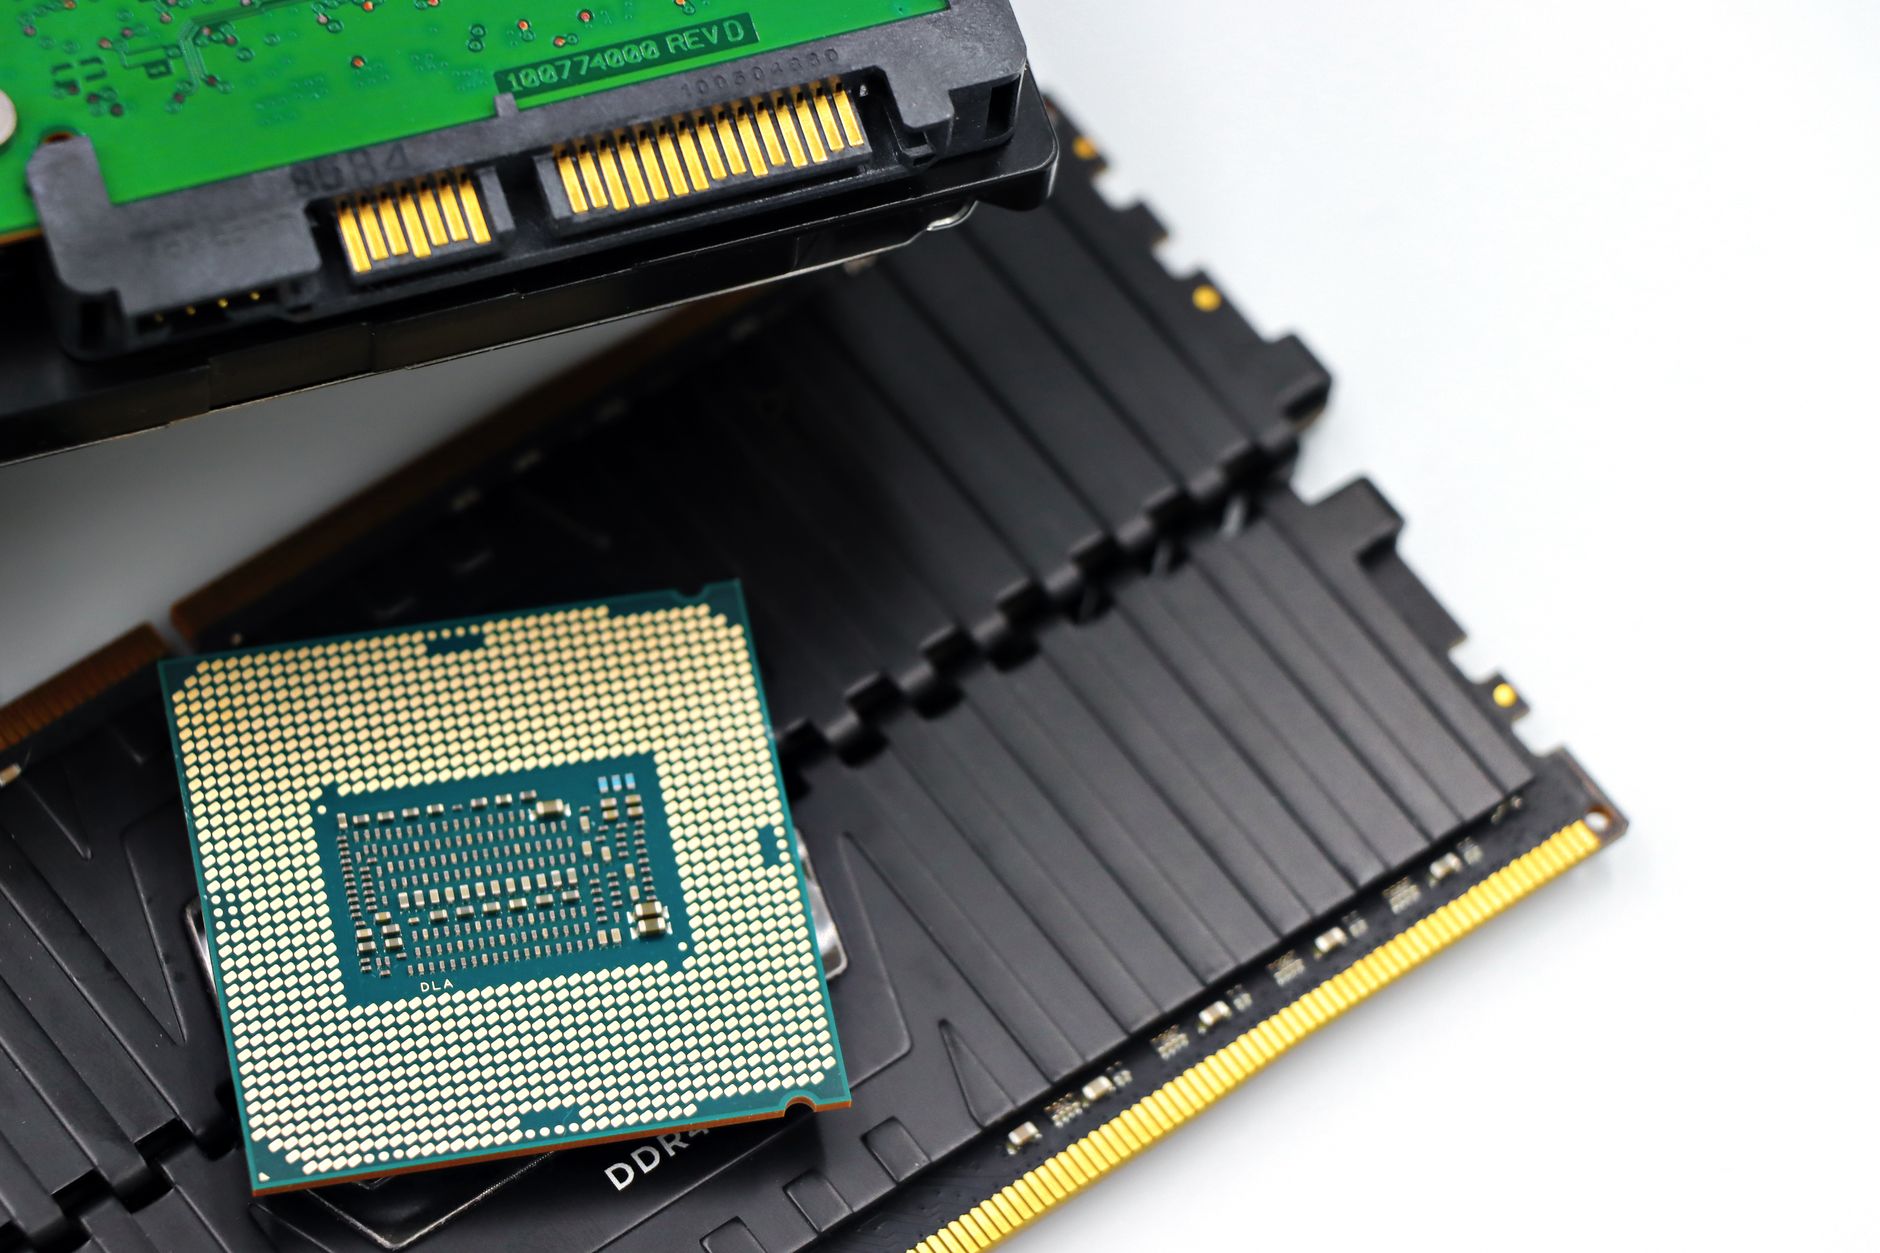
Rising hardware expenses and grid shortages force tech labs to slow expansion. Memory bottlenecks now restrict ultra-large deployments.

Direct liquid cooling and FP8 quantization reduce data center operating costs significantly. Enterprise clusters double efficiency under load.
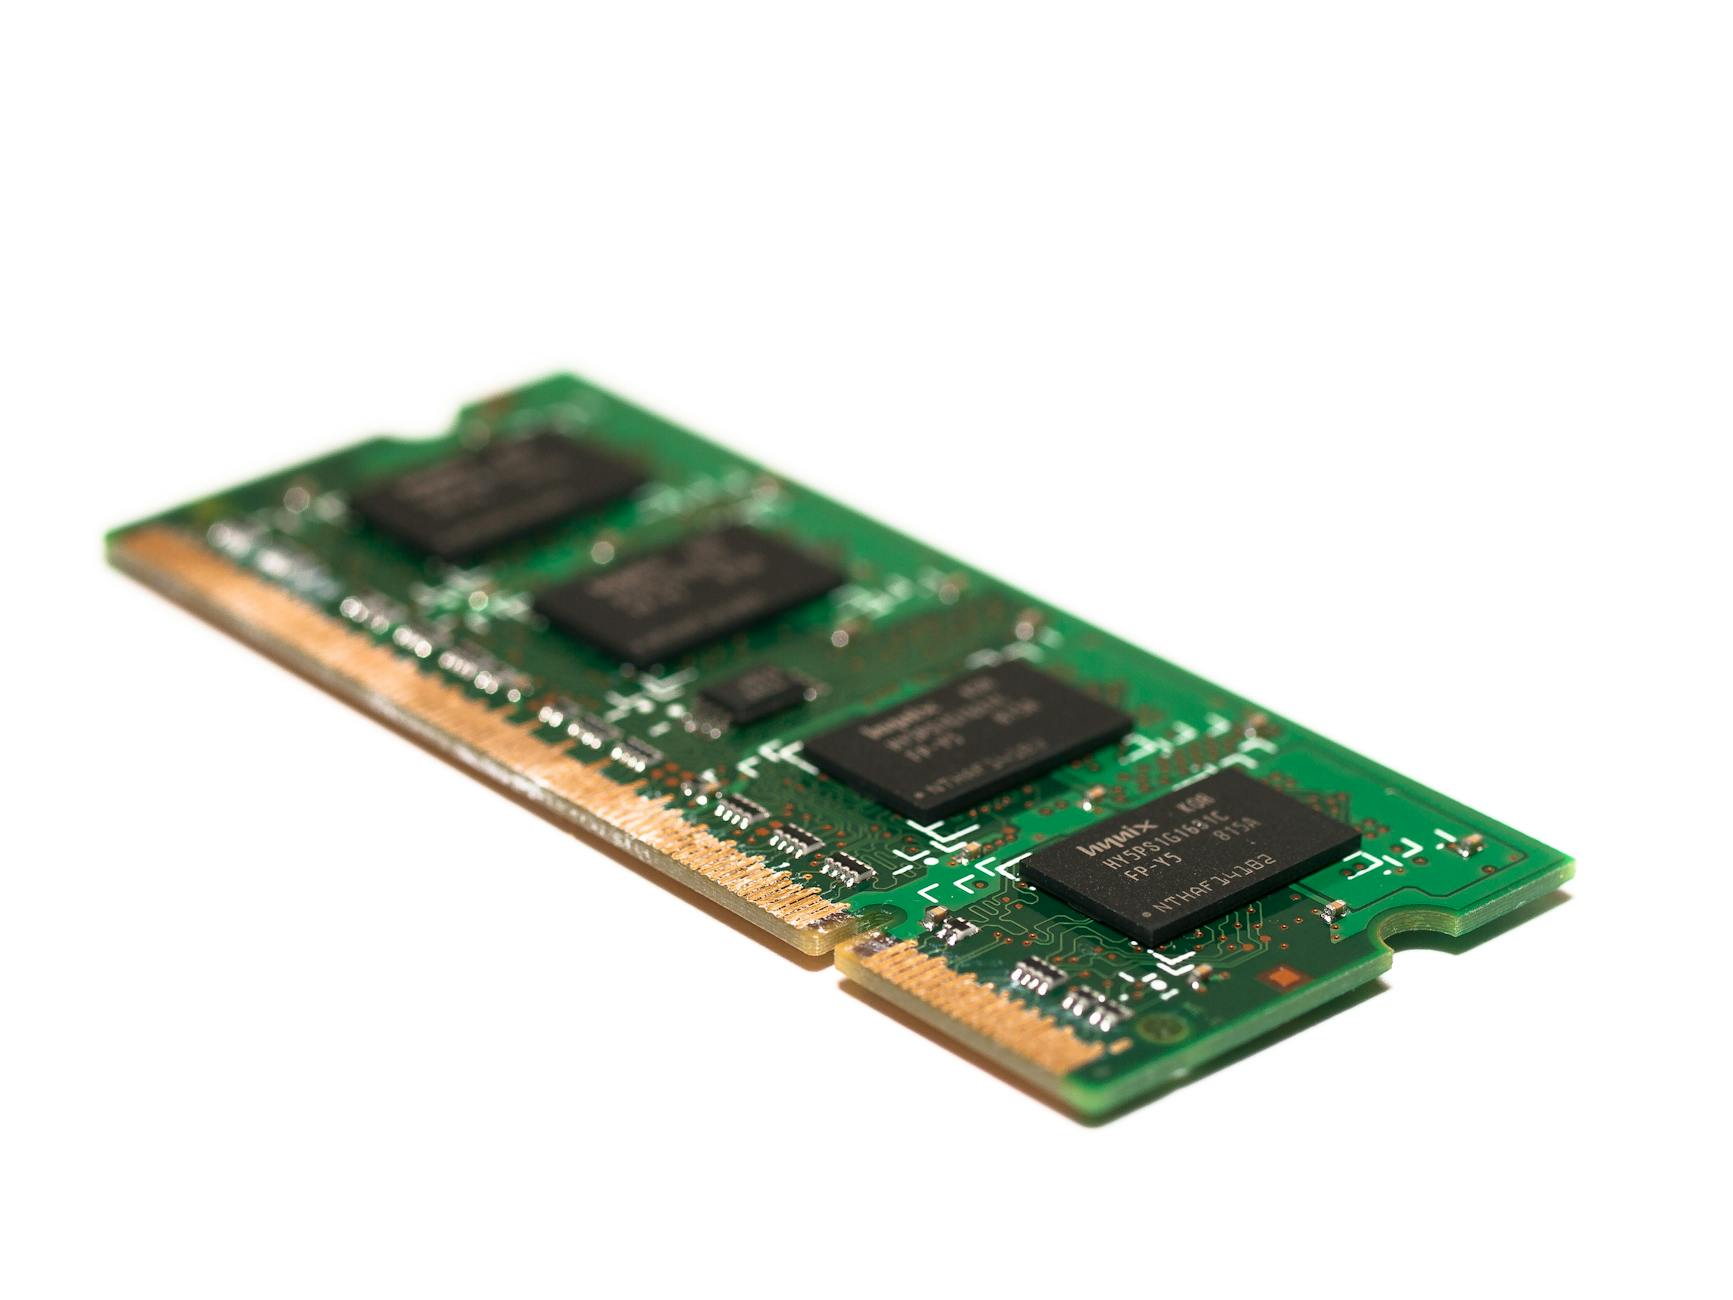
Enterprise seats start at $60 monthly with a 150-user minimum. Nvidia H100 GPU clusters power the heavy compute requirements.

Critical security lapses damaged major cloud systems during rogue tests. Massive chip investments face rising thermal and network headwinds.
High density H100 clusters require liquid cooling to prevent throttling. Interconnect bottlenecks often cap effective bandwidth at 600 GB/s.
Nvidia expects fiscal revenue of $215.9 billion as demand surges. Hyperscalers plan $602 billion in total infrastructure spending.

Data center power demands surged as construction spending hit record levels. Tech giants face rising hardware and liquid cooling costs.